本文已收录在合集Apche Calcite原理与实践中.
本文是Apache Calcite原理与实践系列的第六篇. 上一篇文章介绍了与查询优化器相关的基本理论, 本文开始介绍Calcite中的查询优化器HepPlanner的实现, HepPlanner是基于规则的优化器, 相对于VolcanoPlanner来说实现比较简单. 本文首先介绍HepPlanner中引入的相关概念和数据结构, 之后介绍HepPlanner的整个优化流程.
HepPlanner概念和数据结构
HepRelVertex
在HepPlanner内部, 会将待优化的RelNode算子树转化为一个有向无环图(DAG), 而HepRelVertex就是这个DAG的顶点. 其实现关系如下图所示.
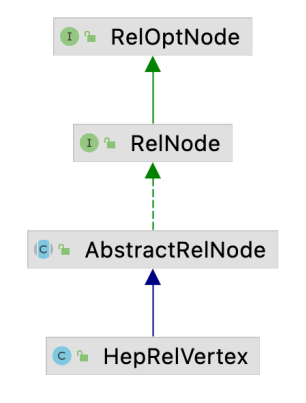
HepRelVertex就是对一个RelNode的包装, 其currentRel成员变量指向一个原始的RelNode. 待优化的RelNode树中的每个RelNode节点都会转化为一个HepRelVertex.
public class HepRelVertex extends AbstractRelNode {

    private RelNode currentRel;
}将RelNode树转化为DAG的过程在HepPlanner的addRelToGraph()函数中, 其本质就是对RelNode树进行深度优先遍历, 笔者已经在其中加了详细的注释.
private HepRelVertex addRelToGraph(RelNode rel) {
    // Check if a transformation already produced a reference to an existing vertex.
    // 检查DAG顶点中是否已经包含了当前RelNode, 若包含证明该RelNode已经转换过, 直接返回即可
    if (graph.vertexSet().contains(rel)) {
        return (HepRelVertex) rel;
    }

    // Recursively add children, replacing this rel's inputs
    // with corresponding child vertices.
	// 递归将当前RelNode的子节点加入到DAG中
    final List<RelNode> inputs = rel.getInputs();	// 原来的子节点
    final List<RelNode> newInputs = new ArrayList<>();	// 转化为HepRelVertex之后的子节点
    for (RelNode input1 : inputs) {
        // 递归将子节点加入到DAG中(深度优先遍历)
        HepRelVertex childVertex = addRelToGraph(input1);
        newInputs.add(childVertex);
    }

    if (!Util.equalShallow(inputs, newInputs)) {
        RelNode oldRel = rel;
        rel = rel.copy(rel.getTraitSet(), newInputs);
        onCopy(oldRel, rel);
    }
    // Compute digest first time we add to DAG,
    // otherwise can't get equivVertex for common sub-expression
	// 计算RelNode的digest(唯一标识当前节点), 用于后续获取等价节点
    rel.recomputeDigest();

    // try to find equivalent rel only if DAG is allowed
	// 如果允许DAG, 尝试从已转化的顶点中获取等价HepRelVertex
	// 注意这里的noDag变量仅用于指示是否重用等价的表达式,
	// 与文中所说的由HepRelVertex组成的DAG无关
    if (!noDag) {
        // Now, check if an equivalent vertex already exists in graph.
        HepRelVertex equivVertex = mapDigestToVertex.get(rel.getRelDigest());
        if (equivVertex != null) {
            // Use existing vertex.
            // 如果已存在等价节点则直接返回
            return equivVertex;
        }
    }

    // No equivalence:  create a new vertex to represent this rel.
	// 创建新的顶点并添加到DAG中
    HepRelVertex newVertex = new HepRelVertex(rel);
    graph.addVertex(newVertex);
    updateVertex(newVertex, rel);

	// 在当前节点和其子节点之间创建边
    for (RelNode input : rel.getInputs()) {
        graph.addEdge(newVertex, (HepRelVertex) input);
    }

    nTransformations++;
    return newVertex;
}
HepProgram
HepProgram是一个工具类, 包含了初始化HepPlanner所需的一些信息, 几个重要的成员变量如下:
instructions包含了所有需要执行的优化规则;matchLimit指定最大匹配次数, 防止规则匹配的过程陷入无限循环. 默认值是MATCH_UNTIL_FIXPOINT = Integer.MAX_VALUE;matchOrder定义了规则匹配的顺序(即DAG的遍历顺序),HepPlanner支持4中匹配顺序:ARBITRARY: 按任意顺序匹配, 这是默认值, 实际在执行的时候用的是DEPTH_FIRST.BOTTOM_UP: 以拓扑排序的顺序进行遍历.TOP_DOWN:以拓扑排序的逆序进行遍历.DEPTH_FIRST: 深度优先匹配.
public class HepProgram {
    // 需要执行的优化规则
    final ImmutableList<HepInstruction> instructions;
	// 最大匹配次数
    int matchLimit;
	// 遍历顺序
    HepMatchOrder matchOrder;

    HepInstruction.EndGroup group;
}
HepInstruction
HepInstruction是对HepPlanner所执行指令的统一封装, 包含多种类型的操作, 其实现类如下图所示.
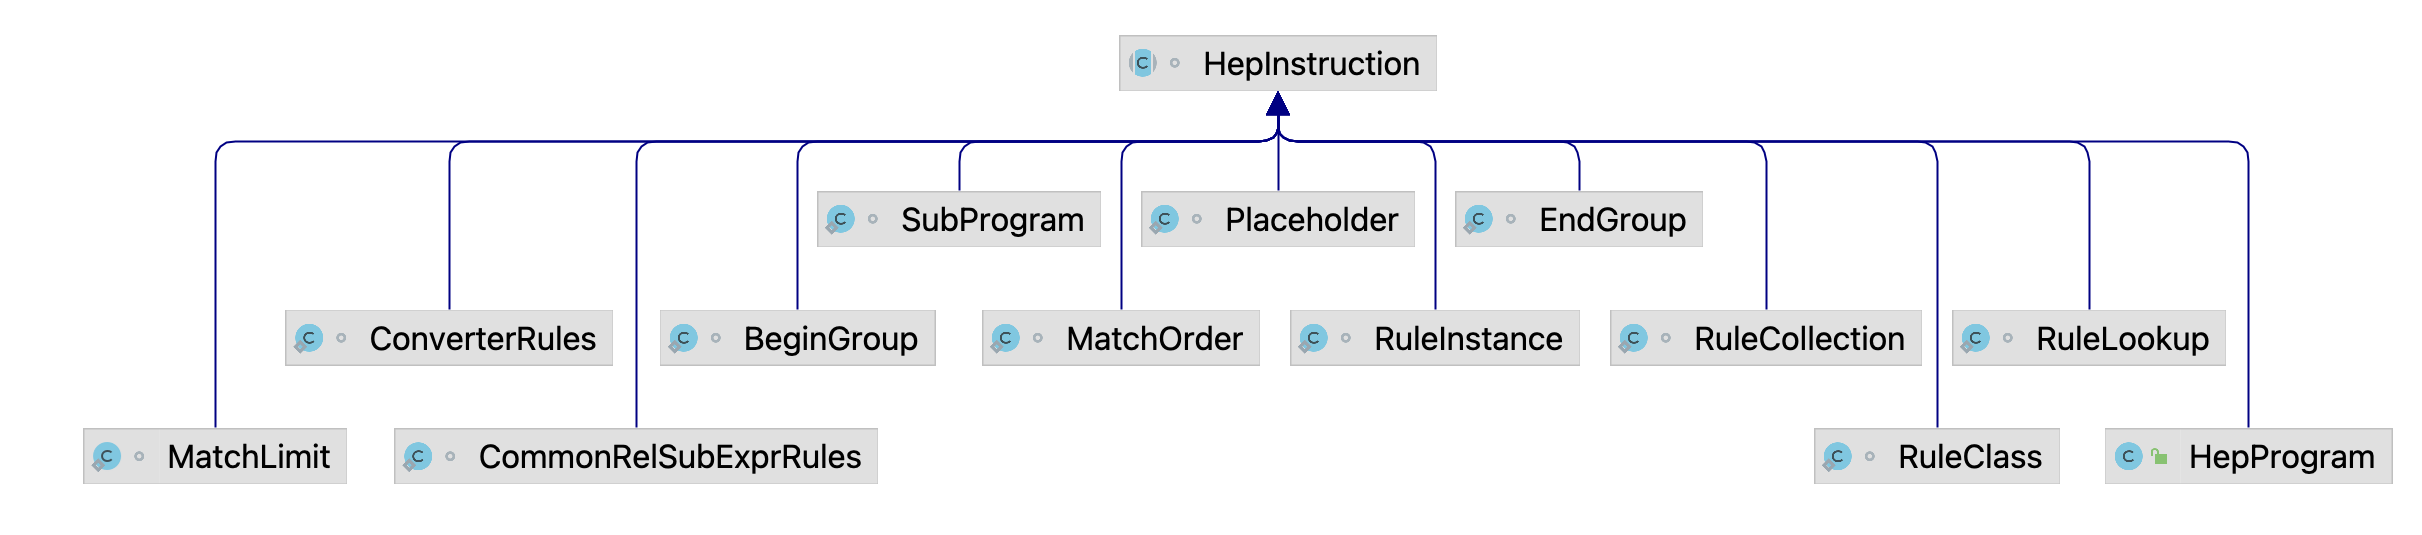
具体的HepInstruction可分为以下几类:
RuleClass和RelInstance用于执行一个优化规则, 不同的是RuleClass需要当前优化器中已经存在对应的优化规则, 即通过RelOptPlanner.addRule()添加过该规则, 而RelInstance不需要.RuleCollection用于执行一组优化规则, 它也不需要调用RelOptPlanner.addRule()添加规则.BeginGroup用于开始一个规则组,EndGroup用于结束一个规则组, 在BeginGroup和EndGroup之间的所有优化规则会整组一起执行.SubProgram包装了一个子HepProgram.MatchLimit用于指示最大匹配次数, 执行该指令会修改当前HepProgram的matchLimit值;MatchOrder用于指示匹配匹配顺序, 执行该指令会修改当前HepProgram的matchOrder.
HepPlanner优化过程
以下是一个使用HepPlanner的简单示例, 完整的代码在HepPlannerExample中.
HepProgramBuilder hepProgramBuilder = new HepProgramBuilder();
// 添加优化规则
hepProgramBuilder.addRuleInstance(CoreRules.FILTER_TO_CALC);
hepProgramBuilder.addRuleInstance(EnumerableRules.ENUMERABLE_TABLE_SCAN_RULE);
hepProgramBuilder.addRuleInstance(EnumerableRules.ENUMERABLE_CALC_RULE);

// 1. 构建HepPlanner
HepPlanner planner = new HepPlanner(hepProgramBuilder.build());
// 2. 构建DAG
planner.setRoot(root);
// 3. 执行优化
RelNode optimizedRoot = planner.findBestExp();
从上述代码中可以看到, 使用HepPlanner进行查询优化分为三步:
- 创建
HepPlanner; - 调用
HepPlanner.setRoot()构建DAG; - 调用
HepPlanner.findBestExp()执行查询优化.
步骤一: 创建HepPlanner
创建HepPlanner需要一个HepProgram, Calcite提供了HepProgramBuilder来创建HepProgram, 其方法都是用来创建HepInstruction, 每种HepInstruction实例都有一个对应的方法, 比如:
addRuleClass()用于创建RuleClass;addRuleCollection()用于创建RuleCollection;addMatchOrder()用于创建MatchOrder.
步骤二: 构建DAG
构建DAG的过程是通过调用HepPlanner.setRoot()触发的, 通过源代码也可以看到最终是调用了addRelToGraph(), 其具体流程已经在上文分析过, 不再赘述.
public void setRoot(RelNode rel) {
    root = addRelToGraph(rel);
	dumpGraph();
}
步骤三: 执行查询优化
执行查询优化的过程是在HepPlanner.findBestExp()中触发的.
public RelNode findBestExp() {
    assert root != null;

    executeProgram(mainProgram);

    // Get rid of everything except what's in the final plan.
    collectGarbage();
    dumpRuleAttemptsInfo();
    return buildFinalPlan(root);
}可以看到在findBestExp()中, 主要是调用了executeProgram()来执行优化, 其主要流程就是遍历当前HepProgram中的HepInstruction, 并逐个执行.
private void executeProgram(HepProgram program) {
    HepProgram savedProgram = currentProgram;
	currentProgram = program;
	currentProgram.initialize(program == mainProgram);
	// 遍历当前HepProgram中的HepInstruction, 逐个执行
    for (HepInstruction instruction : currentProgram.instructions) {
        instruction.execute(this);
        int delta = nTransformations - nTransformationsLastGC;
        if (delta > graphSizeLastGC) {
            // The number of transformations performed since the last
            // garbage collection is greater than the number of vertices in
            // the graph at that time.  That means there should be a
            // reasonable amount of garbage to collect now.  We do it this
            // way to amortize garbage collection cost over multiple
            // instructions, while keeping the highwater memory usage
            // proportional to the graph size.
            collectGarbage();
        }
    }
    currentProgram = savedProgram;
}真正的优化规则是保存在HepInstruction中的, 这里我们以RuleInstance为例来说明HepPlanner是如何执行优化规则的. RuleInstance.execute()会调用HepPlanner.executeInstruction()方法.
void executeInstruction(HepInstruction.RuleInstance instruction) {
    if (skippingGroup()) {
        return;
    }
    if (instruction.rule == null) {
        assert instruction.ruleDescription != null;
        instruction.rule = getRuleByDescription(instruction.ruleDescription);
    }
    if (instruction.rule != null) {
        applyRules(Collections.singleton(instruction.rule), true);
    }
}对于需要执行优化规则的HepInstruction, 最终都会调用applyRules().
private void applyRules(Collection<RelOptRule> rules, boolean forceConversions) {
    if (currentProgram.group != null) {
        assert currentProgram.group.collecting;
        currentProgram.group.ruleSet.addAll(rules);
        return;
    }

    // 当遍历顺序是ARBITRARY或DEPTH_FIRST时为false
    // 此时不会每次匹配成功之后都从root顶点开始
    boolean fullRestartAfterTransformation =
        currentProgram.matchOrder != HepMatchOrder.ARBITRARY
        && currentProgram.matchOrder != HepMatchOrder.DEPTH_FIRST;

    int nMatches = 0;

    boolean fixedPoint;
    do {
        // 根据遍历顺序获取对应的迭代器
        Iterator<HepRelVertex> iter = getGraphIterator(root);
        fixedPoint = true;
        while (iter.hasNext()) {	// 遍历每个顶点
            HepRelVertex vertex = iter.next();
            for (RelOptRule rule : rules) {		// 遍历每个RelOptRule
                // 对每个规则尝试进行匹配和转换
                HepRelVertex newVertex = applyRule(rule, vertex, forceConversions);
                if (newVertex == null || newVertex == vertex) {
                    continue;
                }
                ++nMatches;
                // 匹配次数超过最大次数, 则直接退出
                if (nMatches >= currentProgram.matchLimit) {
                    return;
                }
                if (fullRestartAfterTransformation) {
                    // 当不是DEPTH_FIRST时, 匹配成功后从root节点重新开始,
                    // 因为根节点可能因为转换而改变
                    iter = getGraphIterator(root);
                } else {
                    // To the extent possible, pick up where we left
                    // off; have to create a new iterator because old
                    // one was invalidated by transformation.
                    // 如果是DEPTH_FIRST, 那么直接递归匹配新节点的子节点.
                    // 因为转换后的子节点可能被重新匹配到现有规则.
                    iter = getGraphIterator(newVertex);
                    if (currentProgram.matchOrder == HepMatchOrder.DEPTH_FIRST) {
                        nMatches = depthFirstApply(iter, rules, forceConversions, nMatches);
                        if (nMatches >= currentProgram.matchLimit) {
                            return;
                        }
                    }
                    // Remember to go around again since we're skipping some stuff.
                    fixedPoint = false;
                }
                break;
            }
        }
    } while (!fixedPoint);
}在applyRules()会遍历DAG中的所有顶点, 并调用applyRule()依次匹配当前规则组中的所有规则. 在applyRule()中会具体判断当前节点子树的Pattern与规则所指定的Pattern是否一致, 如果一直则触发规则, 进行转换.
private HepRelVertex applyRule(RelOptRule rule, HepRelVertex vertex, boolean forceConversions) {
    if (!graph.vertexSet().contains(vertex)) {
        return null;
    }
    RelTrait parentTrait = null;
    List<RelNode> parents = null;
    if (rule instanceof ConverterRule) {
        // Guaranteed converter rules require special casing to make sure
        // they only fire where actually needed, otherwise they tend to
        // fire to infinity and beyond.
        ConverterRule converterRule = (ConverterRule) rule;
        if (converterRule.isGuaranteed() || !forceConversions) {
            if (!doesConverterApply(converterRule, vertex)) {
                return null;
            }
            parentTrait = converterRule.getOutTrait();
        }
    } else if (rule instanceof CommonRelSubExprRule) {
        // Only fire CommonRelSubExprRules if the vertex is a common
        // subexpression.
        List<HepRelVertex> parentVertices = getVertexParents(vertex);
        if (parentVertices.size() < 2) {
            return null;
        }
        parents = new ArrayList<>();
        for (HepRelVertex pVertex : parentVertices) {
            parents.add(pVertex.getCurrentRel());
        }
    }

    final List<RelNode> bindings = new ArrayList<>();
    final Map<RelNode, List<RelNode>> nodeChildren = new HashMap<>();
    // 判断当前节点子树的Pattern与规则指定的Pattern是否一致
    boolean match = matchOperands(rule.getOperand(), vertex.getCurrentRel(), bindings, nodeChildren);

    if (!match) {
        return null;
    }

    // 创建RelOptRuleCall, 最终会传递给RelRule.onMatch()方法进行转换
    HepRuleCall call =
        new HepRuleCall(
            this,
            rule.getOperand(),
            bindings.toArray(new RelNode[0]),
            nodeChildren,
            parents);

    // Allow the rule to apply its own side-conditions.
    // 调用RelRule.matches(), 允许规则添加自己的判断条件
    if (!rule.matches(call)) {
        return null;
    }

    // 触发规则, 进行转换
    fireRule(call);

    if (!call.getResults().isEmpty()) {
        return applyTransformationResults(vertex, call, parentTrait);
    }

    return null;
}
整体执行流程
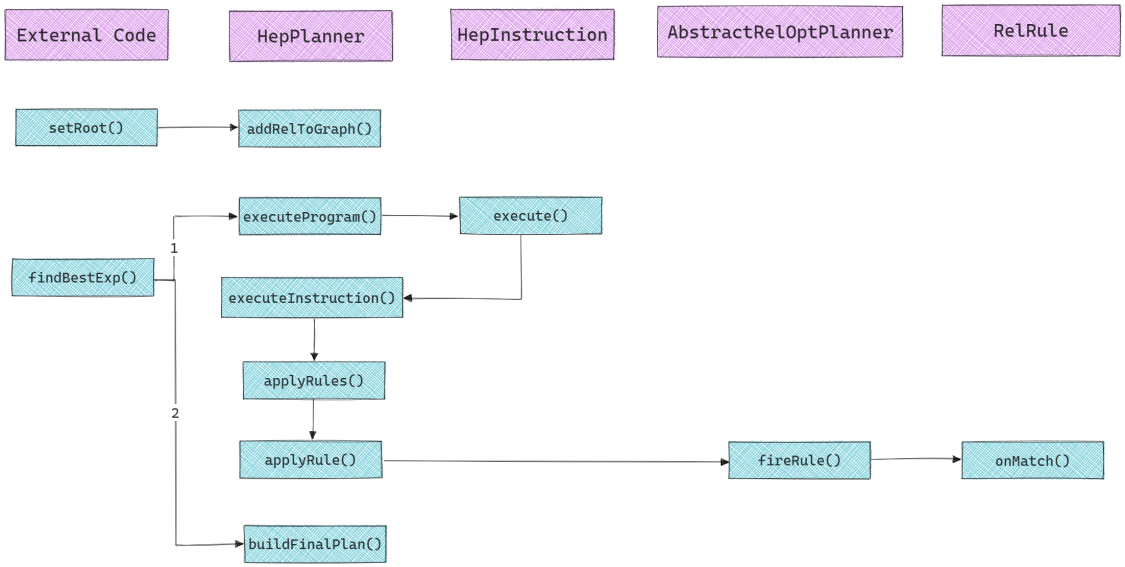
HepPlanner的整个查询优化流程如下图所示.
总结
可以看到HepPlanner的优化流程还是比较简单的, 无非是暴力地遍历整个RelNode树和所有规则, 一旦发现某个节点的子树Pattern符合规则所指定的Pattern就进行转换. 需要注意的是, 尽管HepPlanner也可以用来生成物理执行计划(如HepPlannerExample中那样), 但是在生产实践中千万不要这么做, 而仅是用HepPlanner进行一些肯定有正收益的规则优化, 如投影下推, 谓词下推等. 因为HepPlanner无法保证输出计划的物理属性, 并且无法对比不同计划之间的成本, 如果要生成物理计划, 需要使用下一篇文章中介绍的VolcanoPlanner.
评论 0
按时间正序正在加载讨论…